Skip Lists#
A skip list is a probabilistic data structure that implements the Map abstract data type. It utilizes randomness to achieve average search, insertion, and deletion performance of \(O(\lg n)\), which is comparable to balanced binary search trees. The fundamental concept is to create a multi-level structure that permits a binary-search-like traversal of a standard linked list.
The “Express Lane” Analogy#
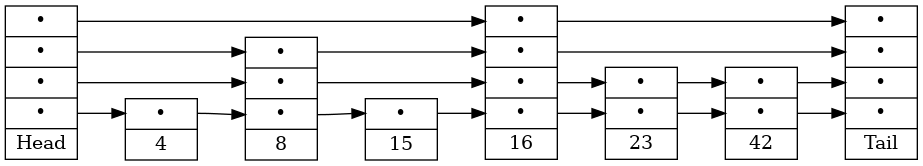
The structure of a skip list can be visualized using an “express lane” analogy. A standard, sorted linked list (level 0) represents the “local” lane, which visits every node. A skip list adds multiple “express” lanes (level 1, level 2, etc.) above this base list. These higher-level lists are sparser and skip over nodes.
A node that exists in the base list may also appear in one or more express lanes, forming a “tower” of nodes. These express lanes allow the search algorithm to bypass large segments of the list at once.
Search#
To perform a get() or contains() operation, the search begins at the highest, sparsest express lane (the top-left corner of the structure). The algorithm traverses rightward along the current level as long as the next node’s key is less than the target key.
If the next node’s key is greater than or equal to the target key (or the end of the list is reached at that level), the algorithm drops down one level and continues its rightward traversal. This process is repeated, moving right and dropping down, until the key is found in the base list (level 0) or the search determines the key is not present.
The pseudocode for this operation is as follows:
def contains(K key):
  for each level from top to bottom
    while (next.key < key)
      move right
  # After loops, we are at the node preceding the potential key
  if (next.key == key)
    return True
  else
    return False
Insertion#
To insert(), we follow the same path through the list as we do when
accessing a node. Once we’re on the bottom of the layers, and looking at the
node just to the left of where our new element will be, we add our new node.
We then flip a coin (choose a random number between 0 and 1, if it’s less than
.5 it’s a heads, if larger, it’s a tails). If it’s heads, we add a layer to
the new node, and connect it to the node just to the left of it on that layer.
We continue flipping and connecting until we get a tails.
Perfect vs. Randomized Skip Lists#
Perfect Skip Lists#
An “ideal” or “perfect” skip list would be structured precisely like a balanced binary search tree. Each higher level would contain exactly half the nodes of the level below it, perfectly arranged to divide the search space in half at each step.

In this perfect configuration, the height of the tallest tower would be \(O(\lg n)\), and the get() operation would also be \(O(\lg n)\), mirroring a true binary search.
The significant limitation of this perfect structure is maintenance. Performing an insertion or deletion while preserving this perfect balance would require, in the worst case, rebuilding large portions of the list, an \(O(n)\) operation that negates the search efficiency.
Randomized Skip Lists#
To avoid the \(O(n)\) cost of maintaining a perfect structure, randomized skip lists use probability to approximate the ideal arrangement. The goal is to maintain the desired statistical properties of a perfect list: approximately 50% of nodes should have height 1 (base list only), 25% height 2, 12.5% height 3, and so on.
This process (a 50% chance at each step) naturally produces the desired geometric distribution of tower heights.
Analysis of Randomized Skip Lists#
The runtime of a get() operation depends on the vertical distance traveled (the list’s maximum height) and the horizontal distance traveled (the nodes visited at each level).
1. Height Analysis#
The height of any single tower has no theoretical upper bound, as a very long sequence of “heads” is possible, though highly improbable. We can, however, analyze the probability of the entire list’s maximum height.
The probability of any specific tower reaching height \(i\) is \(P_i = 1/2^{i-1}\).
The expected number of nodes of height \(i\) in a skip list of \(n\) nodes is therefore \(n(\frac{1}{2})^{i-1}\).
If we set this equal to 1, we can solve for the height where we expect only one node to be that height. This gives us \(i=\log_2(n)+1\), so the expected height of the tallest node is \(O(\log(n))\).
2. Horizontal Analysis#
A search or insertion requires us to not only move down through the layers of the towers, but also across. So, we must also analyze the expected number of horizontal steps taken at each level. When the search algorithm drops from level \(i\) down to level \(i-1\), it is because the next tower at level \(i\) was too large. The search then proceeds rightward at level \(i-1\).
The algorithm will stop its horizontal traversal at level \(i-1\) when it reaches the next tower that has a height of at least \(i\). How many nodes at level \(i-1\) exist (on average) between two nodes of level \(i\)? Since every node that successfully reached height \(i-1\) had a \(1/2\) probability of also extending to height \(i\), we expect to traverse \(1 / (1/2) = 2\) nodes at level \(i-1\) before encountering the next tower of height \(i\).
This means the expected work in the inner loop (horizontal traversal at any given level) is \(O(1)\), or constant time.
3. Total Runtime#
The total expected runtime for a get() operation is the product of the number of levels (the height) and the expected work per level. This gives a total expected runtime of \(O(\lg n) \times O(1) = O(\lg n)\).
Conclusion#
Skip lists work wonderfully anywhere you might use a BST. They are faster, smaller, and easier to implement than a self-balancing BST… probably.